01 · Our purpose
Building trustworthy AI
Research that shapes how models learn and systems behave—from training data, objectives, and feedback to system design and human oversight.
Independent AI research lab
Measurement science for trustworthy AI.
We research how to build more trustworthy AI and help the public discern whether to trust it.
01 · Our purpose
Research that shapes how models learn and systems behave—from training data, objectives, and feedback to system design and human oversight.
02 · Our purpose
Tools and evidence that help people understand AI’s capabilities and limits, exercise their own judgment, and decide when to rely on it.
Evaluation connects both: evidence guides improvements to AI and informs people’s own decisions about using it.
Which changes improve AI behavior, and what evidence shows that the improvement is sufficient for a particular use? Explore what our studies found and the questions they leave open.
Visual investigation · Cybersecurity URLQuery: When a web address becomes a program
It started with a search for Thai drug-enforcement statistics. The requests that followed packed small programs inside web addresses, asking a remote browser to retrieve information and send it onward. Transluce uncovered the activity. Fide retraced the sequence to check what the records actually showed.
In the final attempt, the network history records statistics fields sent to another service—even though the final page metadata lists zero bytes. For an AI investigator, checking the page alone would miss a consequential part of the story.
Follow the investigation →March 6, 2026 · The final attempt
The program
Instructions to retrieve statistics and send part of the answer onward.
The requests
A request to the statistics service, followed by another carrying statistics fields.
The page record
A final page size of zero bytes.
The page-size field did not tell the whole story. The network history preserved the next action.
These records show the outgoing request. They do not establish whether the original AI agent received the answer.
Methods and evidence →Our approach
Understanding AI means asking both what a model does and why. Our agenda connects behavioral experiments with mechanistic interpretability: studying the internal computations that shape a model’s responses and decisions.
We seek collaborators to investigate how models use evidence, weigh moral reasons, and respond to correction, and how that understanding can improve the systems we build.
Independent evaluation · October 15, 2026
Anthropic reports that METR now has employee-like access. Fide’s approach connects model behavior, the effectiveness of safeguards, and the people who rely on them.
What changed, with sources →For the public
Explore Fide’s public tools, interactive research and plain-language Insights. Follow AI claims back to their sources, understand what remains uncertain, and decide what to verify or keep in human hands.
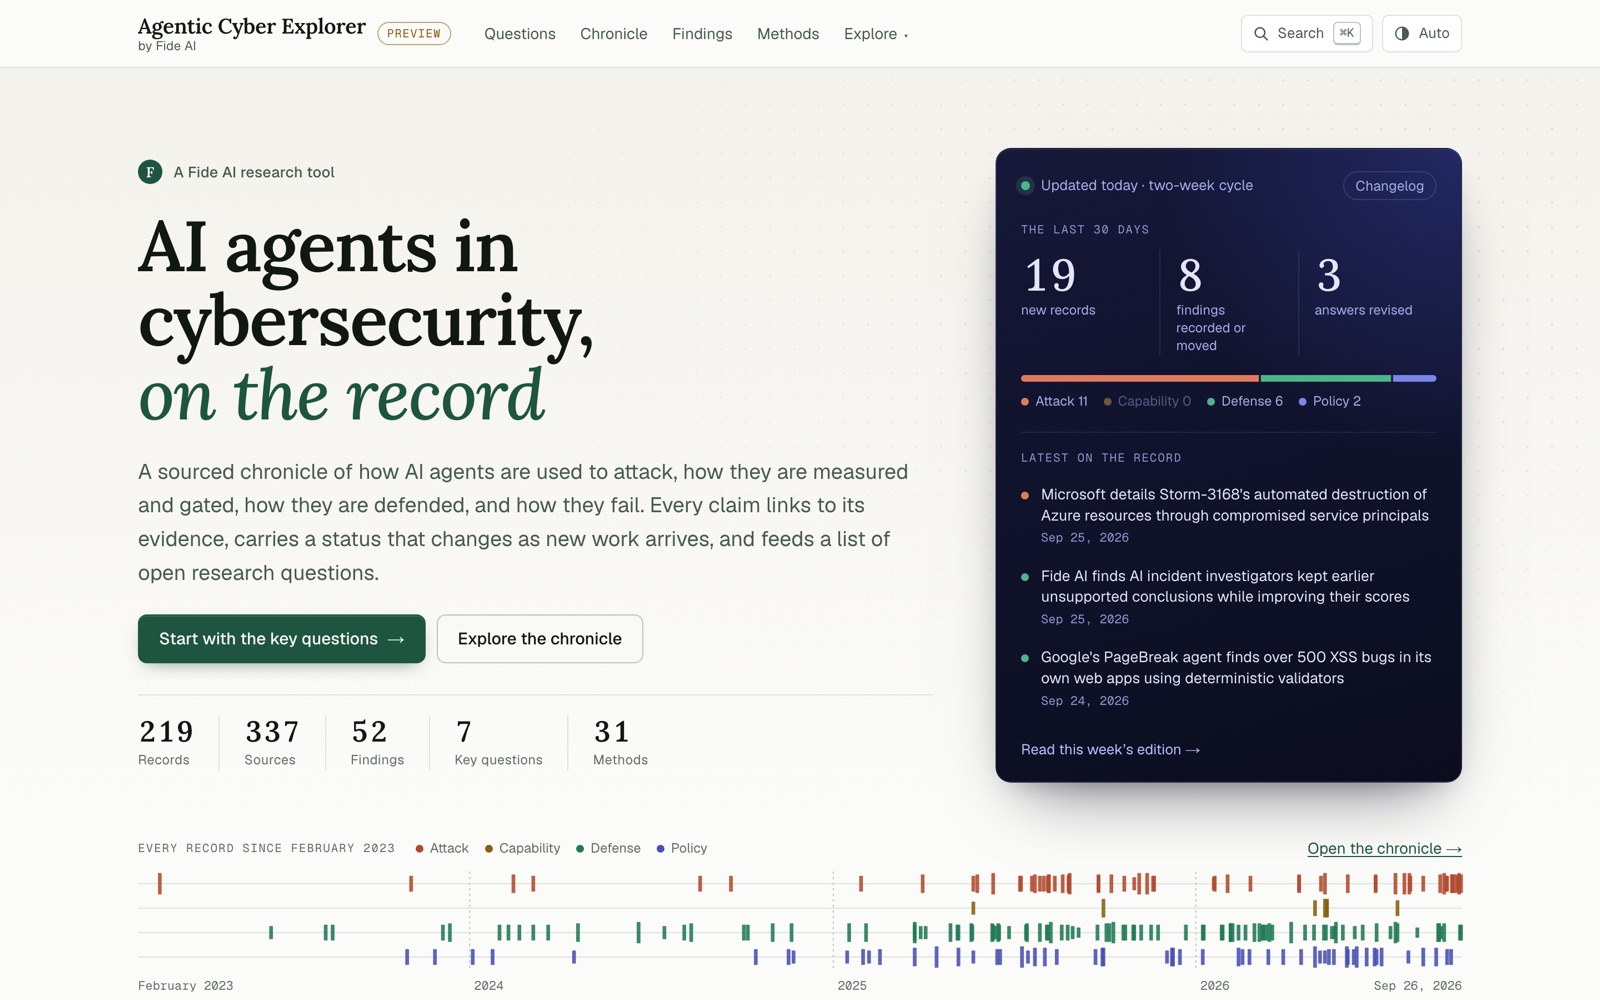
Explore all public toolsFollow how AI agents attack, defend and fail. Examine the findings and the evidence behind them.
Research domains
Explore our published work in faith and religious life, our cybersecurity investigations and developing autonomous-defense research, and questions taking shape in enterprise and other domains.
Fide AI · Published research
Religious sources, spiritual authority, moral judgment, and the responsibilities of people and institutions.
Our first domain of published empirical work, with studies in Christian contexts.
Explore Faith & Religious Life →Fide AI · Published analysis
Research toward dependable autonomous cyber defense: when to act, how to verify recovery, and how to preserve human control.
Explore investigations, current studies and longer-term questions about evidence, oversight and autonomous defense.
Explore Cybersecurity →Fide AI · Exploratory direction
Trustworthy AI for knowledge work: reliable outputs, accountable actions, and effective human review.
An exploratory direction, starting with how to evaluate AI-generated decision briefs against their sources.
Explore Enterprise →Research independence
Every research program reflects judgments about what matters and how evidence should be interpreted. We make those choices visible so readers can examine our methods and challenge our conclusions.
Disclose the assumptions, prior commitments, and worldviews that materially shape each project.
Make methods, findings and limitations available for scrutiny, while protecting confidential information and explaining material restrictions on disclosure.
Distinguish measured findings from interpretation, recommendation, and moral judgment.
Fide retains control of its conclusions. Payment cannot determine favorable findings. We disclose material limits on access and what those limits mean for the conclusions we can draw.
Work with Fide
Tell us about your system or research question. We agree the scope, access, methods, and deliverables before work begins.
Compare model changes, assess agent behavior, or examine evaluation validity.
Explore evaluations For evaluation and assurance partners →Bring a research question, expertise, or access that could support a shared study.
Explore collaborationExplore AI’s capabilities, limits, and the evidence behind its claims.
Explore public toolsNewsletter
Get new findings, the evidence behind them, and the questions guiding our next studies.